I kept seeing the same problem in a different form: I knew I was using language models a lot, but I did not have a useful answer to where the usage went.
A monthly total is easy to find. It is much harder to answer questions like:
- How much of yesterday’s usage was implementation versus research?
- Which models account for most of the spend?
- Is a large token count actually expensive, or was it generated locally or through a free route?
- Am I spending more because I am doing more work, or because I am using a more expensive model?
So I built a small token tracker for my desktop.
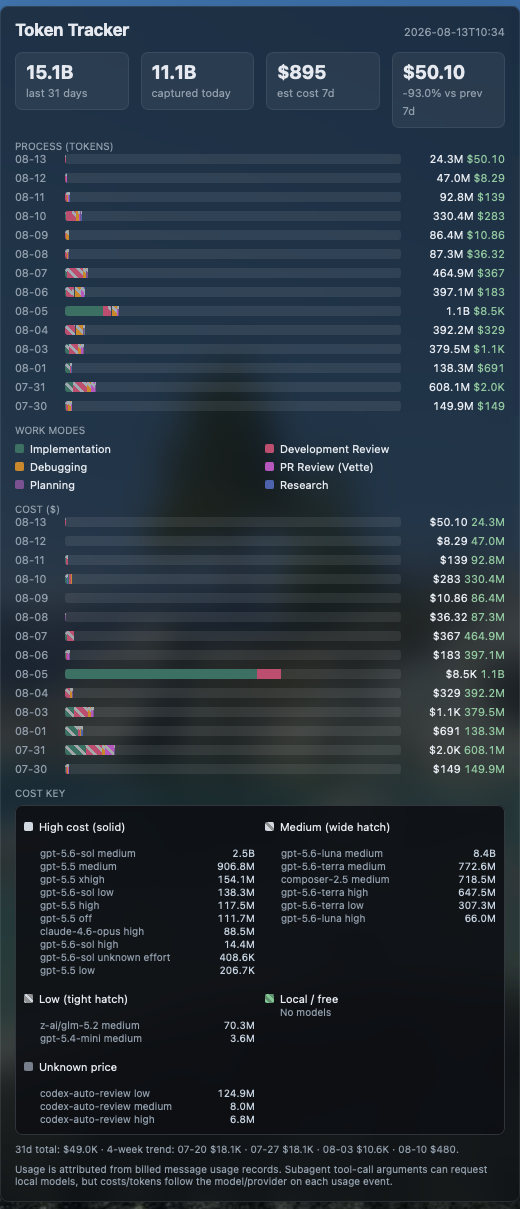
What it tracks
The tracker combines billed message usage with local session records and presents them in two complementary views:
- Process view shows token volume by day.
- Cost view shows the same days normalized by estimated cost.
Each bar is split by work mode. Implementation, planning, research, debugging, review, and operations get their own colors, while hatching communicates the model’s price band. That distinction matters: a short session on an expensive model can cost more than a much larger local session.
The dashboard also keeps a model-level cost key. It makes the assumptions visible instead of hiding them in a single total: high-cost models are solid, medium-cost models use wide hatching, low-cost models use tight hatching, and local or free usage is marked separately.
The important classification boundary
The first version treated every session as if it came from one source. That made totals look complete while making it difficult to understand which tool produced them.
The tracker now treats agent-runtime sessions as a first-class input alongside the existing command-line records. Both sources use the same usage-event shape, so they can share parsing, pricing, and work-mode classification without being collapsed into one anonymous stream.
That separation is useful even when the underlying model is the same. The model explains price; the source explains workflow.
Why work modes are heuristic
There is no perfect classifier in the session data. A session can move from planning to implementation, or from implementation to debugging, and the prompt text does not always say so explicitly.
For now, the tracker uses a deliberately boring rule: inspect session metadata and user messages for a small ordered set of keywords, then assign the first matching mode. Review-specific terms win before general review terms; debugging wins before the default implementation bucket.
This is not intended to be a universal taxonomy. It is an instrument for noticing patterns. If the categories stop helping me make decisions, they should change.
The practical lesson
The most useful metric is not “tokens used.” It is the relationship between:
- tokens — how much context and generation I consumed;
- cost — what that usage is estimated to be worth; and
- mode — what kind of work I was doing.
Those three dimensions make the dashboard actionable. If research is expensive, I can tighten research prompts. If debugging dominates, I can improve the test loop. If implementation is cheap locally but slow, I can decide whether the trade-off is worthwhile.
The tracker is intentionally small. It reads existing local records, renders a static report, and feeds a desktop widget. There is no new service to operate and no separate logging workflow to remember.
That is the real goal: not perfect accounting, but enough visibility to make better decisions about how I use these tools.